
RDF#
This chapter is a short introduction to RDF using rudof.
Preliminaries: install and configure rudof#
%pip install -q "pyrudof>=0.3.22"
%pip install -q plantuml
Note: you may need to restart the kernel to use updated packages.
Note: you may need to restart the kernel to use updated packages.
The main entry point is the
Rudof class, a
stateful session through which most of the functionality is provided. Calling Rudof()
with no arguments starts a session with the default configuration; a
RudofConfig
can be passed to customize it (see the getting started chapter).
from pyrudof import Rudof, RudofConfig, ResultDataFormat

rudof = Rudof()
Throughout this chapter we visualize small graphs by asking rudof for a PlantUML rendering and turning it into an image. The following helper does that in one call, so the examples below stay about RDF rather than about plumbing.
import subprocess
import sys
from pathlib import Path

from IPython.display import Image


def render_puml(puml, name="out"):
    """Turn a PlantUML string into a PNG and display it."""
    Path(f"{name}.png").unlink(missing_ok=True)
    Path(f"{name}.puml").write_text(puml, encoding="utf-8")

    subprocess.run(
        [sys.executable, "-m", "plantuml", f"{name}.puml"],
        check=True,
        capture_output=True,
    )
    return Image(f"{name}.png")


def show_graph(session, name="out"):
    """Render the RDF data currently loaded in `session` as a diagram."""
    return render_puml(session.serialize_data(ResultDataFormat.PlantUML), name)
The RDF data model#
RDF describes the world with statements, also called triples, of the form
<subject> <predicate> <object>. Predicates are always identified by IRIs, and in the most
basic form subjects and objects are IRIs too. An example is
<http://example.org/alice> <http://example.org/knows> <http://example.org/bob>, which
says that Alice knows Bob.
The simplest RDF syntax, N-Triples, is exactly that: one triple per line, each ended by a dot. In rudof we can load one as follows:
rudof.read_data("<http://example.org/alice> <http://example.org/knows> <http://example.org/bob> .")
An RDF graph is a set of triples, so adding more statements is just a matter of
writing them one after another. Note that read_data defaults to merging into what is
already loaded, so the triples below are added to the one above rather than replacing it.
rudof.read_data("""
  <http://example.org/alice> <http://example.org/knows> <http://example.org/carol> .
  <http://example.org/alice> <http://example.org/worksFor> <http://example.org/acme> .
  <http://example.org/alice> <http://example.org/birthPlace> <http://example.org/spain> .
  <http://example.org/carol> <http://example.org/knows> <http://example.org/bob> .
  <http://example.org/bob> <http://example.org/knows> <http://example.org/alice> .
""")
Calling the graph a set is not a technicality: it is why RDF integrates well. The union of two RDF graphs is another RDF graph, with no reconciliation step, because the nodes that appear in both are identified by the same IRIs.
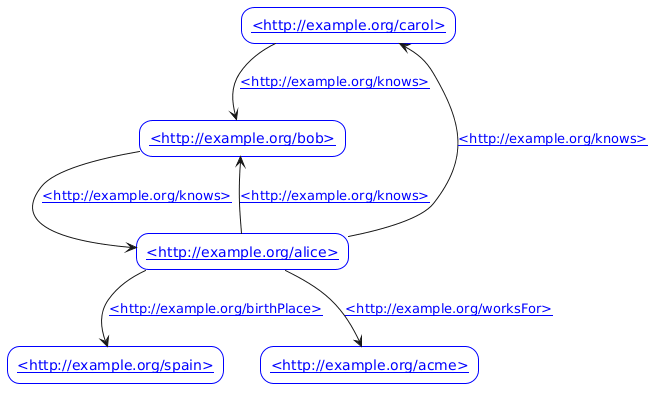
rudof can draw small graphs, which is a good way to see the shape of what we just loaded:
show_graph(rudof)
Reusing vocabularies#
Making up IRIs under http://example.org/ is fine for a tutorial, but it produces data
that nobody else can interpret. Interoperability comes from reusing the IRIs of agreed
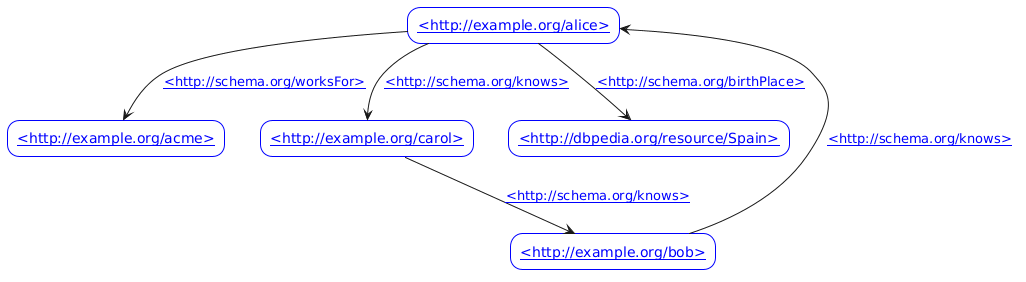
vocabularies. Here we swap our invented predicates for
schema:knows,
schema:worksFor and
schema:birthPlace from
Schema.org, and use
DBpedia’s IRI for Spain instead of our own.
rudof.reset_all()
rudof.read_data("""
  <http://example.org/alice> <http://schema.org/knows>      <http://example.org/carol> .
  <http://example.org/alice> <http://schema.org/worksFor>   <http://example.org/acme> .
  <http://example.org/alice> <http://schema.org/birthPlace> <http://dbpedia.org/resource/Spain> .
  <http://example.org/carol> <http://schema.org/knows>      <http://example.org/bob> .
  <http://example.org/bob>   <http://schema.org/knows>      <http://example.org/alice> .
""")

show_graph(rudof)
Prefix declarations and qualified names#
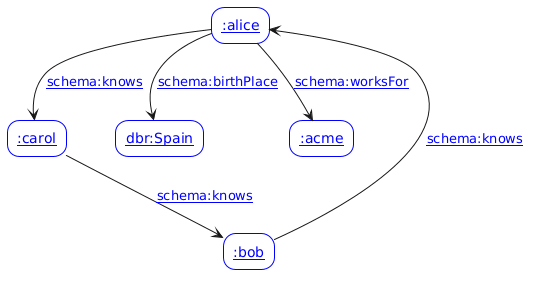
Full IRIs make documents hard to read. Turtle lets you
declare a prefix for an IRI namespace and then write prefix:name instead of the whole
thing. The previous graph, rewritten:
rudof.reset_all()
rudof.read_data("""
 prefix : <http://example.org/>
 prefix schema: <http://schema.org/>
 prefix dbr: <http://dbpedia.org/resource/>

 :alice schema:knows :carol .
 :alice schema:worksFor :acme .
 :alice schema:birthPlace dbr:Spain .
 :carol schema:knows :bob .
 :bob   schema:knows :alice .
""")

show_graph(rudof)
Turtle adds more shorthands on top of that: a semicolon repeats the subject of the previous statement, and a comma repeats both the subject and the predicate. The graph below is the same one written more compactly.
rudof.reset_all()
rudof.read_data("""
 prefix : <http://example.org/>
 prefix schema: <http://schema.org/>
 prefix dbr: <http://dbpedia.org/resource/>

 :alice schema:knows      :carol, :bob ;
        schema:worksFor   :acme        ;
        schema:birthPlace dbr:Spain    .
 :carol schema:knows      :bob         .
""")

print(rudof.serialize_data())
@prefix dbr: <http://dbpedia.org/resource/> .
@prefix : <http://example.org/> .
@prefix schema: <http://schema.org/> .
:carol schema:knows :bob .
:alice schema:knows :carol , :bob ;
	schema:worksFor :acme ;
	schema:birthPlace dbr:Spain .
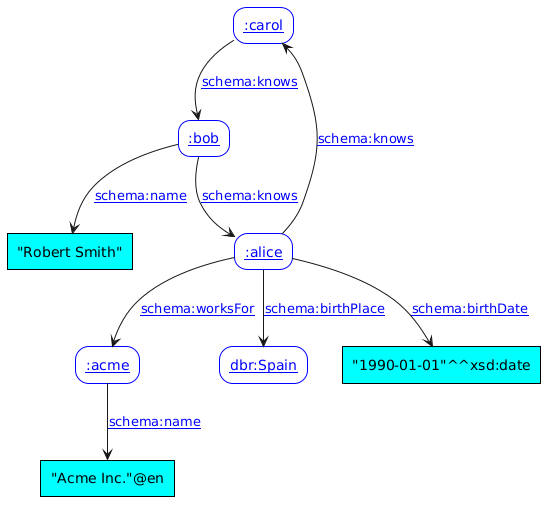
RDF literals#
Apart from IRIs, the object of a triple can be a literal (a constant value). There are three kinds:
plain strings, like
"Robert Smith";language-tagged strings, like
"Spain"@enor"España"@es;typed literals, like
"23"^^xsd:integeror"1990-01-01"^^xsd:date, whose datatype is usually one of the XML Schema datatypes.
Literals can only ever be objects, never subjects or predicates: they are leaves of the graph.
rudof.reset_all()
rudof.read_data("""
 prefix : <http://example.org/>
 prefix schema: <http://schema.org/>
 prefix dbr: <http://dbpedia.org/resource/>
 prefix xsd: <http://www.w3.org/2001/XMLSchema#>

 :alice schema:knows :carol .
 :alice schema:worksFor :acme .
 :alice schema:birthPlace dbr:Spain .
 :alice schema:birthDate "1990-01-01"^^xsd:date .
 :carol schema:knows :bob .
 :bob   schema:name "Robert Smith" .
 :bob   schema:knows :alice .
 :acme  schema:name "Acme Inc."@en .
""")

show_graph(rudof)
Blank nodes#
Sometimes we want to say something about a thing that has no IRI. For example: Alice knows
someone who was born in Italy and works for Acme, without knowing who that someone is.
RDF calls such a node a blank node and writes it _:id.
rudof.reset_all()
rudof.read_data("""
 prefix : <http://example.org/>
 prefix schema: <http://schema.org/>
 prefix dbr: <http://dbpedia.org/resource/>

 :alice schema:knows _:1 .
 _:1 schema:worksFor :acme .
 _:1 schema:birthPlace dbr:Italy .
""")

show_graph(rudof)
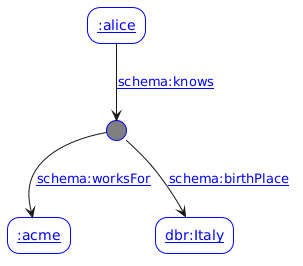
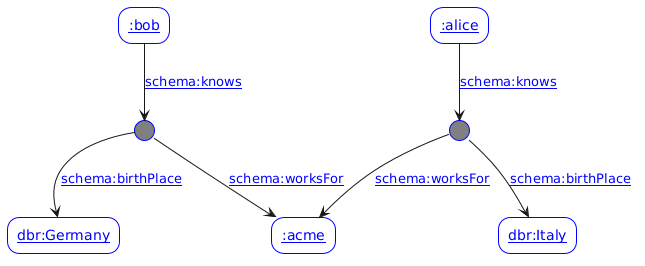
The id in _:id is local to the document. It lets you refer to the same blank node
several times while writing the graph, but it carries no meaning outside it and rudof gives
no guarantee that it is preserved internally. If we now add that Bob knows someone who
works for Acme and was born in Germany, using _:2, we get a second, distinct blank node:
rudof.read_data("""
 prefix : <http://example.org/>
 prefix schema: <http://schema.org/>
 prefix dbr: <http://dbpedia.org/resource/>

 :bob schema:knows _:2 .
 _:2 schema:worksFor :acme .
 _:2 schema:birthPlace dbr:Germany .
""")

show_graph(rudof)
Merging RDF data#
You may have noticed the reset_all() calls above. They are there because read_data
merges by default: the triples it reads are added to whatever the session already
holds. This is the behaviour you want when you assemble a graph from several sources, and
the behaviour you have to remember to undo when you want a clean slate.
rudof.reset_all()
rudof.read_data("""
prefix : <http://example.org/>

:x a :Person     ;
   :name "Alice" ;
   :knows :y     .
:y a :Person     ;
   :name "Bob"   ;
   :knows :x     .
""")

rudof.read_data("""
prefix : <http://example.org/>

:u a :Person     ;
   :name "Dave"  ;
   :knows :x, :y .
""", merge=True)

show_graph(rudof)
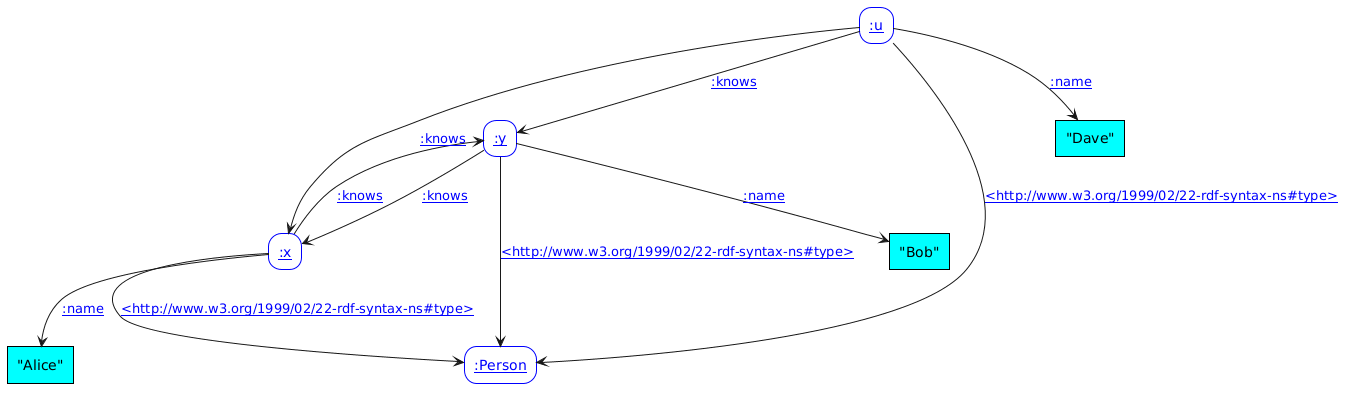
Because :x and :y are the same IRIs in both documents, the two graphs join up at those
nodes. Passing merge=False would instead replace the loaded data with the new document.
Different RDF formats#
The same graph can be written in several concrete syntaxes:
N-Triples: one triple per line, no abbreviations at all. Verbose, but trivial to produce and to stream.
Turtle: N-Triples plus the human-friendly shorthands we have been using: prefixes,
;,,, typed literals.RDF/XML: the original RDF syntax, from when XML was the default interchange format.
JSON-LD: RDF expressed as JSON, designed so that ordinary JSON documents can be read as RDF by adding a
@context.TriG / N-Quads: the Turtle and N-Triples of datasets, which are collections of named graphs rather than a single graph.
rudof reads all of them (RDFFormat) and writes all of them (ResultDataFormat), so it
doubles as a format converter. The format is detected from the file extension when reading
a file, and can always be given explicitly.
print(rudof.serialize_data(format=ResultDataFormat.NTriples))
<http://example.org/u> <http://example.org/knows> <http://example.org/x> .
<http://example.org/u> <http://example.org/knows> <http://example.org/y> .
<http://example.org/u> <http://www.w3.org/1999/02/22-rdf-syntax-ns#type> <http://example.org/Person> .
<http://example.org/u> <http://example.org/name> "Dave" .
<http://example.org/x> <http://example.org/knows> <http://example.org/y> .
<http://example.org/x> <http://www.w3.org/1999/02/22-rdf-syntax-ns#type> <http://example.org/Person> .
<http://example.org/x> <http://example.org/name> "Alice" .
<http://example.org/y> <http://example.org/knows> <http://example.org/x> .
<http://example.org/y> <http://www.w3.org/1999/02/22-rdf-syntax-ns#type> <http://example.org/Person> .
<http://example.org/y> <http://example.org/name> "Bob" .
print(rudof.serialize_data(format=ResultDataFormat.RdfXml))
<?xml version="1.0" encoding="UTF-8"?>
<rdf:RDF xmlns="http://example.org/" xmlns:rdf="http://www.w3.org/1999/02/22-rdf-syntax-ns#" xmlns:its="http://www.w3.org/2005/11/its">
	<rdf:Description rdf:about="http://example.org/u">
		<knows rdf:resource="http://example.org/x"/>
		<knows rdf:resource="http://example.org/y"/>
		<rdf:type rdf:resource="http://example.org/Person"/>
		<name>Dave</name>
	</rdf:Description>
	<rdf:Description rdf:about="http://example.org/x">
		<knows rdf:resource="http://example.org/y"/>
		<rdf:type rdf:resource="http://example.org/Person"/>
		<name>Alice</name>
	</rdf:Description>
	<rdf:Description rdf:about="http://example.org/y">
		<knows rdf:resource="http://example.org/x"/>
		<rdf:type rdf:resource="http://example.org/Person"/>
		<name>Bob</name>
	</rdf:Description>
</rdf:RDF>
print(rudof.serialize_data(format=ResultDataFormat.JsonLd))
[
  {
    "@id": "http://example.org/u",
    "http://example.org/knows": [
      {
        "@id": "http://example.org/x"
      },
      {
        "@id": "http://example.org/y"
      }
    ],
    "http://example.org/name": [
      {
        "@value": "Dave"
      }
    ],
    "http://www.w3.org/1999/02/22-rdf-syntax-ns#type": [
      {
        "@id": "http://example.org/Person"
      }
    ]
  },
  {
    "@id": "http://example.org/x",
    "http://example.org/knows": [
      {
        "@id": "http://example.org/y"
      }
    ],
    "http://example.org/name": [
      {
        "@value": "Alice"
      }
    ],
    "http://www.w3.org/1999/02/22-rdf-syntax-ns#type": [
      {
        "@id": "http://example.org/Person"
      }
    ]
  },
  {
    "@id": "http://example.org/y",
    "http://example.org/knows": [
      {
        "@id": "http://example.org/x"
      }
    ],
    "http://example.org/name": [
      {
        "@value": "Bob"
      }
    ],
    "http://www.w3.org/1999/02/22-rdf-syntax-ns#type": [
      {
        "@id": "http://example.org/Person"
      }
    ]
  }
]
ResultDataFormat also offers output formats that are not RDF syntaxes at all
(PlantUML, Svg and Png) which is what the show_graph helper above uses.
Looking at a node#
When exploring an unfamiliar graph, the question is usually not “give me every triple” but
“what does this node look like?”. node_info answers that by printing the neighbourhood
of a node: its outgoing arcs (where it is the subject) and its incoming arcs (where it is
the object).
rudof.reset_all()
rudof.read_data("""
prefix : <http://example.org/>
prefix xsd: <http://www.w3.org/2001/XMLSchema#>

:alice a :Person ;
 :name      "Alice"                ;
 :birthDate "2005-03-01"^^xsd:date ;
 :worksFor  :acme                  ;
 :knows     :bob                   .
:bob a :Person   ;
 :name      "Robert Smith"         ;
 :birthDate "2003-01-02"^^xsd:date ;
 :worksFor  :acme                  ;
 :knows     :alice                 .
:acme a :Company ;
 :name "Acme Inc." .
""")

print(rudof.node_info(":alice"))
Outgoing arcs
:alice
├─── :birthDate ─► "2005-03-01"^^xsd:date
├─── :knows ─► :bob
├─── :name ─► "Alice"
├─── :worksFor ─► :acme
└─── <http://www.w3.org/1999/02/22-rdf-syntax-ns#type> ─► :Person

Incoming arcs
:alice
▲
└─── :knows ── :bob
The mode argument restricts the listing to one direction:
print(rudof.node_info(":alice", mode="incoming"))
Incoming arcs
:alice
▲
└─── :knows ── :bob
And a list of predicates filters the arcs down to the ones you care about:
print(rudof.node_info(":alice", [":worksFor", ":knows"]))
Outgoing arcs
:alice
├─── :knows ─► :bob
└─── :worksFor ─► :acme

Incoming arcs
:alice
▲
└─── :knows ── :bob
Walking a neighbourhood in code#
node_info returns a string meant for a human to read. When you want to process the
neighbourhood instead, node_neighborhood yields the same arcs as objects, each with a
direction, a predicate, a neighbor and the depth at which it was found.
for arc in rudof.node_neighborhood(":alice", depth=1):
    print(f"{str(arc.direction):8} {arc.predicate:34} -> {arc.neighbor}")
Outgoing http://example.org/birthDate       -> "2005-03-01"^^xsd:date
Outgoing http://example.org/knows           -> http://example.org/bob
Outgoing http://example.org/name            -> "Alice"
Outgoing http://example.org/worksFor        -> http://example.org/acme
Outgoing http://www.w3.org/1999/02/22-rdf-syntax-ns#type -> http://example.org/Person
Incoming http://example.org/knows           -> http://example.org/bob
The arcs are materialized before the iterator is handed back, so breaking out of the loop
early does not save any work on a node with a large fan-out. That is what the limit
argument is for, and the truncated flag on the iterator tells you whether the limit
actually cut anything off, which is how you distinguish “that was all of them” from
“there is more where that came from”.
capped = rudof.node_neighborhood(":alice", depth=1, limit=3)
arcs = [f"{arc.predicate} -> {arc.neighbor}" for arc in capped]
print(f"{len(arcs)} arcs, more available: {capped.truncated}")

whole = rudof.node_neighborhood(":alice", depth=1, limit=50)
print(f"{len(list(whole))} arcs, more available: {whole.truncated}")
3 arcs, more available: True
6 arcs, more available: False
Against a remote endpoint#
Neither method needs the data to be local. If the session is pointed at a SPARQL endpoint,
node_info becomes a quick way to look at a node in a public knowledge graph.
dbpedia = Rudof()
dbpedia.read_data(endpoint="https://dbpedia.org/sparql")

print(dbpedia.node_info(node_selector="dbr:Oviedo", predicates=["foaf:depiction"]))
Outgoing arcs
dbr:Oviedo
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/1._Iglesia_San_Julián_de_los_Prados_(35752657690).jpg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/15._Junta_General_del_Principado_de_Asturias_(36143894785).jpg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/Ayuntamiento-de-oviedo.jpg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/Catedral_de_Oviedo_03.jpg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/Ceremonia_de_entrega_de_los_Premios_Príncipe_de_Asturias_2010.jpg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/Church_of_San_Isidoro_el_Real,_Oviedo_16.jpg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/Día_de_América_en_Asturias-2015_35.jpg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/Escudo_de_Oviedo.svg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/Estadio_Municipal_Carlos_Tartiere_(Real_Oviedo_S.A.D.).jpg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/Fachada_principal_del_Teatro_Campoamor.jpg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/La-Regenta-y-Catedral.jpg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/Locomotora_de_vapor_nº_4_de_Fábrica_de_Mieres_en_el_Naranco,_que_llevaba_el_mineral_de_hierro_desde_el_Naranco_hasta_la_Estación_del_Norte_de_Oviedo,_ca._1895_(Museo_del_Ferrocarril_de_Asturias).jpg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/Mapa_Parroquial_Uviéu_(color).jpg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/Museo_arte_oviedo.jpg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/Ortofotomapa_Asturias_2010-OVIEDO_CENTRO.jpg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/Ortofotomapa_Asturias_2010-OVIEDO_ESTE.jpg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/Ortofotomapa_Asturias_2010-OVIEDO_OESTE.jpg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/Oviedo,_Espanha_-_panoramio_(9).jpg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/Oviedo-Plaza_del_Fontán.jpg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/Oviedo-_Teatro_Campoamor.jpg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/Oviedo-ayuntamiento4.jpg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/Oviedo02.jpg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/Oviedo_Landscape_(230140305).jpeg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/Oviedo_Uría.jpg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/Oviedo_cartel.jpg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/Oviedo_desde_el_monte_Naranco.jpg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/Real_Monasterio_de_San_Pelayo_(Oviedo).jpg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/San_Miguel_de_Lillo_01.jpg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/Santa_María_Naranco.jpg>
├─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/Santa_María_del_Naranco._Oviedo.jpg>
└─── foaf:depiction ─► <http://commons.wikimedia.org/wiki/Special:FilePath/Uvieu_flag.svg>
node_infocan be simulated with SPARQL queries (see the next chapter). It is worth having anyway, as a low-ceremony way to inspect the neighbourhood of a node when what you are really doing is working out how to validate it.
A worked example#
The following graph appears in a number of rudof’s presentations. It describes :timbl, a
node standing for Tim Berners-Lee: born in London in 1955, working for CERN, and knowing
someone from Spain.
rudof.reset_all()
rudof.read_data("""
prefix :       <http://example.org/>
prefix xsd:    <http://www.w3.org/2001/XMLSchema#>
prefix rdf:    <http://www.w3.org/1999/02/22-rdf-syntax-ns#>
prefix rdfs:   <http://www.w3.org/2000/01/rdf-schema#>

:timbl  rdf:type    :Human ;
        rdfs:label  "Tim Berners-Lee" ;
        :birthPlace :london ;
        :birthDate  "1955-06-08"^^xsd:date ;
        :employer   :CERN ;
        :knows      _:1 .
_:1     :birthPlace :Spain .
:CERN   rdf:type    :Organization .
:london rdf:type    :City, :Metropolis ;
        :country    :UK .
""")

show_graph(rudof)
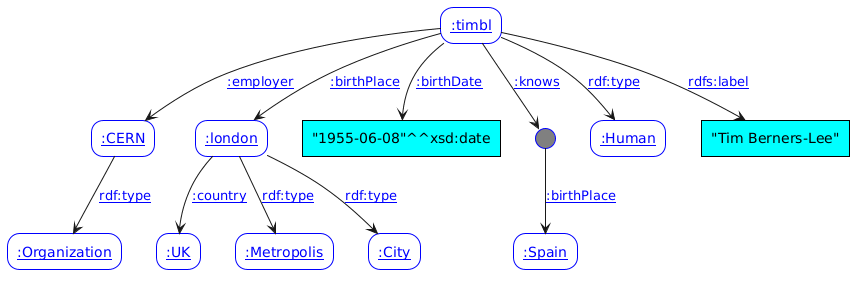
Notice what this graph does not say. Nothing requires :timbl to have a label, or forbids
a second :birthDate, or says that the object of :employer should be an
:Organization. RDF will happily accept data that breaks every one of those expectations.
Writing those expectations down (and checking data against them) is what the
ShEx and SHACL chapters are about.
References#
RDF 1.1 Primer - the gentle introduction from W3C.
RDF 1.1 Concepts and Abstract Syntax - the normative definition of the data model.
Turtle, N-Triples, JSON-LD - the concrete syntaxes used above.
RDF 1.2 - the next chapter but one, on statements about statements.